My Month with the Z.ai GLM Coding Plan (Pro, $64/mo): 9.6 Billion Tokens
9.63B tokens / $64 month the number that matters here
By Stan K.
Personal experience: 30 days on a real Z.ai GLM Pro subscription under a 10–12h/day agent workload — 9.63B tokens, 92.5% cache hit, 473K credits, nearly 2× the official quota. How much was bonuses, what the same volume costs on API prices, and why the number is a ceiling, not a promise.
Every coding-plan comparison on the internet copies the marketing table. This one is different: we ran a real subscription — Z.ai GLM Pro, paid $192 for three months ($64/month) — through a 10–12 hour/day agent workload, then opened the dashboard and audited every number against the official quota and published API prices.
What 30 days actually looked like
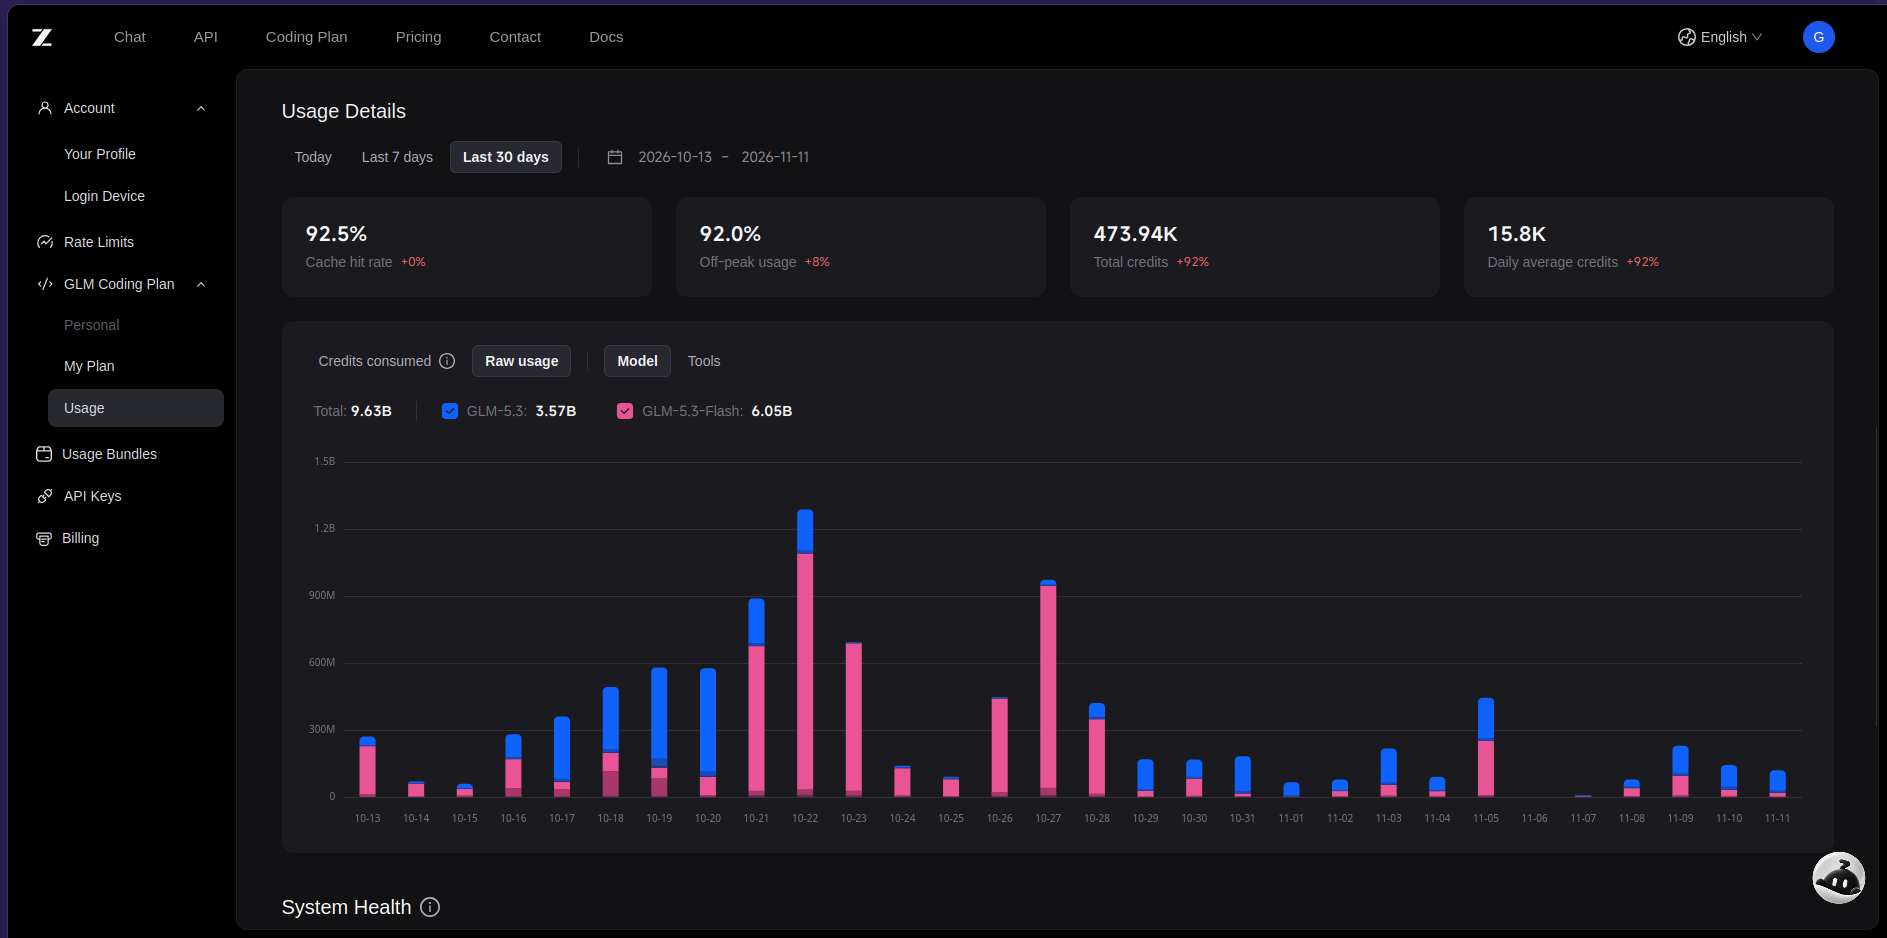
Straight from the account dashboard (Oct 13 – Nov 11, 2026):
- Total usage: 9.63B tokens — GLM-5.3: 3.57B (37%), GLM-5.3-Flash: 6.05B (63%)
- Cache hit rate: 92.5% (cached input / uncached input / output split roughly 90 / 8 / 2)
- Off-peak usage: 92% — Z.ai charges full credits only 14:00–18:00 Singapore time on weekdays; a US workday sits almost entirely in the 50%-off window
- Credits consumed: 473.94K (15.8K/day average)
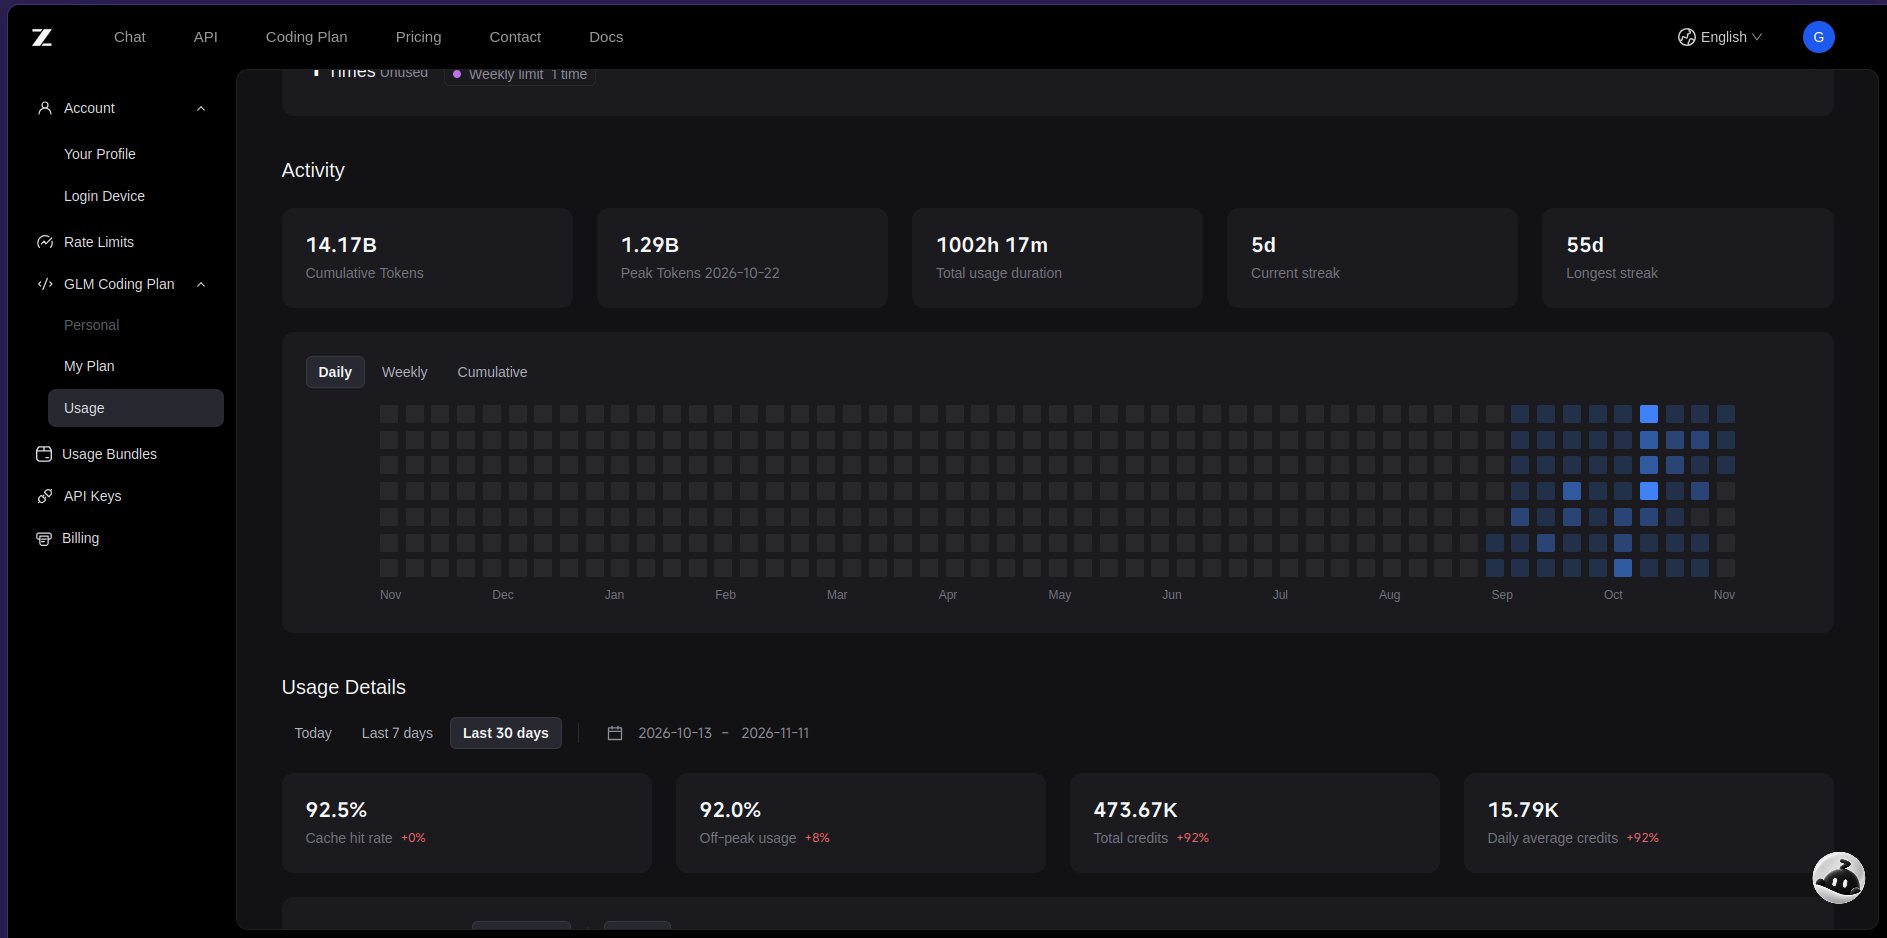
- Over the full 55 days since subscribing: 14.17B tokens, 1,002 hours of usage, peak day 1.29B (Oct 22)
The number that doesn’t add up — and why
Here’s the catch, and we won’t hide it: the official Pro quota is 12,000 credits per 5 hours and 60,000 per week — about 240K credits a month. The account burned 473.94K. Almost double.
The difference is bonuses. Z.ai hands out Quota Reset Cards (official, documented in their FAQ — they expire on their own schedule) and ran a promotion giving 300M free GLM-5.3-Flash tokens daily (documented in r/ZaiGLM, Oct 27 2026). Stack those on a US-timezone off-peak discount and you get 9.63B tokens that the sticker quota doesn’t explain. Our arithmetic: ~5.9B tokens from credits at the effective off-peak rate, plus roughly 3.7B from bonus Flash tokens — which lands almost exactly on the dashboard total.
The 9.6B-month was measured during a generous bonus regime. Reset cards carry validity periods, the daily Flash bonus has no published end date, and Z.ai already reworked the entire plan to credits-based billing in July 2026 — legacy plans are no longer sold. Without bonuses, the same $64/month buys roughly 1.6–3.2B tokens (peak-rate vs off-peak). Treat 9.63B as a ceiling observed once, not a promise.
What the same volume would cost on API
Same 9.63B tokens, same 90/8/2 split, same two models — priced at per-1M list rates:
| Where | GLM-5.3 prices (in/cached/out) | Cost for 3.57B | Cost for 6.05B Flash | Total |
|---|---|---|---|---|
| Z.ai API direct | $1.40 / $0.26 / $4.40 | ~$1,549 | ~$296 ($0.15/$0.03/$0.50) | ~$1,845 |
| OpenRouter (Wafer host) | $0.0699 / $0.0689 / $1.40 | ~$341 | ~$192 ($0.0399/$0.03/$0.0784) | ~$533 |
So the month cost $64 and delivered between 8× (OpenRouter prices) and 29× (Z.ai list prices) its price in tokens. Strip the bonuses and assume the floor quota — 1.6B tokens — and the honest multiplier lands around 3–10×. That’s still the best token-per-dollar we’ve measured at our coding-plans ranking, which is exactly why Z.ai sits at the top of the volume column despite a privacy record we score harshly elsewhere.
Why the cache rate is the real hero
The dirty secret of that 9.6B month: it’s mostly cheap tokens. At a 92.5% cache hit, the overwhelming majority of input is billed at the cached multiplier — roughly 4× cheaper than fresh input, and output (the expensive part) is only ~2% of volume. An agent session that keeps its context prefix identical turn after turn, plus a workload parked in off-peak hours, is what turns a $64 subscription into billions of tokens. The same behavior on a plan with opaque limits buys you nothing — see how to read coding-plan quotas.
The verdict after the audit
If you run agents most of the day, keep cache discipline high, and can live with Z.ai’s data-residency and training-policy terms (we document them in our ZCode review — they are the worst in our agent rankings), the GLM Pro plan is genuinely the most fuel per dollar we can verify. If any of those conditions breaks — light usage, chaotic sessions that miss cache, or a privacy requirement — the math flips, and pay-per-token API often wins.
Measure your own dashboard before believing any of this. That’s the whole point.